
Using GLM-5.2 / GLM-4.7-Flash Models with Claude Code

The Claude Code CLI (claude) isn't limited to Anthropic's own models. By using the Anthropic Messages API-compatible endpoint (the "Anthropic Skin") provided by OpenRouter, you can run any model as the backend. This time I tried a setup that assigns z-ai/glm-5.2 as the main conversation model and z-ai/glm-4.7-flash for lightweight background tasks such as title generation, and I'm summarizing how to do it here.

Reference: https://openrouter.ai/docs/cookbook/coding-agents/claude-code-integration

Prerequisites​

  • $env:OPENROUTER_API_KEY must already be set to your OpenRouter API key.
  • Even if you're logged into Claude Code with a claude.ai account, authentication via environment variables takes priority when present. In that case a warning ⚠ claude.ai connectors are disabled ... appears, but it doesn't affect operation.

Required Environment Variables​

VariableValueNotes
ANTHROPIC_BASE_URLhttps://openrouter.ai/apiOpenRouter's Anthropic-compatible endpoint
ANTHROPIC_AUTH_TOKENYour OpenRouter API keySent as Authorization: Bearer
ANTHROPIC_API_KEY"" (explicitly empty string)If unset or non-empty, authentication methods conflict and cause an error
ANTHROPIC_MODELz-ai/glm-5.2The main conversation model. Specify the OpenRouter model ID as-is
ANTHROPIC_SMALL_FAST_MODELz-ai/glm-4.7-flashSub-model for lightweight background tasks such as title generation

Distinguishing Main and Sub Models​

ANTHROPIC_MODEL only controls the main conversation model. The lightweight, fast sub-model that Claude Code uses internally for things like title generation and auto-mode detection is specified via ANTHROPIC_SMALL_FAST_MODEL. Setting this variable alone reliably switches the model used for lightweight tasks.

Setup Methods​

Configure the following in the repository's .claude/settings.local.json.

{
"env": {
"ANTHROPIC_BASE_URL": "https://openrouter.ai/api",
"ANTHROPIC_API_KEY": "",
"ANTHROPIC_MODEL": "z-ai/glm-5.2",
"ANTHROPIC_SMALL_FAST_MODEL": "z-ai/glm-4.7-flash"
}
}

Don't write ANTHROPIC_AUTH_TOKEN (a secret) into the file — supply it from the shell side via OPENROUTER_API_KEY instead. Add the following once to your PowerShell profile ($PROFILE) and it will be set automatically every time you open a shell afterward.

$env:ANTHROPIC_AUTH_TOKEN = $env:OPENROUTER_API_KEY

For bash/zsh, add this to ~/.bashrc or ~/.zshrc:

export ANTHROPIC_AUTH_TOKEN="$OPENROUTER_API_KEY"

With this in place, running claude -p "..." inside this directory automatically loads the settings from .claude/settings.local.json, and both the main and sub models are used via OpenRouter. Running Claude Code in other projects is unaffected.

Method B: Switch temporarily for a specific command only​

If you don't want to modify your shell profile, specify the environment variables inline when running the command.

PowerShell:

$env:ANTHROPIC_BASE_URL = "https://openrouter.ai/api"
$env:ANTHROPIC_AUTH_TOKEN = $env:OPENROUTER_API_KEY
$env:ANTHROPIC_API_KEY = ""
$env:ANTHROPIC_MODEL = "z-ai/glm-5.2"
$env:ANTHROPIC_SMALL_FAST_MODEL = "z-ai/glm-4.7-flash"
claude -p "1+1は?"

bash:

ANTHROPIC_BASE_URL="https://openrouter.ai/api" \
ANTHROPIC_AUTH_TOKEN="$OPENROUTER_API_KEY" \
ANTHROPIC_API_KEY="" \
ANTHROPIC_MODEL="z-ai/glm-5.2" \
ANTHROPIC_SMALL_FAST_MODEL="z-ai/glm-4.7-flash" \
claude -p "1+1は?"

Persisting the above variables as Windows user environment variables makes OpenRouter/GLM the default in every terminal and project. However, this also affects operations in other projects where you intend to use regular Claude (Anthropic), so Method A/B is recommended unless you actually want to change the global default unintentionally.

Verification​

I confirmed with the following command that z-ai/glm-5.2 is recorded in the response and in the billing log (modelUsage).

claude -p "Reply with exactly: OK-GLM-TEST" --output-format json
{
"result": "OK-GLM-TEST",
"modelUsage": {
"z-ai/glm-5.2": { "inputTokens": 3272, "outputTokens": 8, "costUSD": 0.028336 }
}
}

Also, running a slightly longer prompt with --debug all confirmed that dispatching to both the main model and the sub model actually occurs.

[API:timing] dispatching to firstParty model=z-ai/glm-4.7-flash
[API:timing] dispatching to firstParty model=z-ai/glm-5.2

For a single prompt, the lightweight task correctly goes to z-ai/glm-4.7-flash and the main response correctly goes to z-ai/glm-5.2 — the models are being used properly.

Known Caveat: Request Proliferation in Interactive Sessions​

In an interactive claude session (whether opened from VS Code or launched directly in a TTY), even light input resulted in 13 API calls being recorded within the same minute in OpenRouter's Activity log. Of those, 12 were small calls to the sub model (GLM 4.7 Flash), and only the last one was the main response from the main model (GLM 5.2). Total cost stayed around $0.0094.

On the other hand, I confirmed that a single run via claude -p (non-interactive, print mode) barely causes this proliferation. If you want to keep costs down, using -p is safer. If you regularly use interactive sessions, it's a good idea to set ANTHROPIC_SMALL_FAST_MODEL to route requests to a cheap model while monitoring usage on OpenRouter's Activity dashboard.

Troubleshooting​

  • The warning ⚠ claude.ai connectors are disabled because ANTHROPIC_API_KEY or another auth source is set... can be ignored (it only disables claude.ai's connector feature; the API calls themselves still succeed).
  • Leaving ANTHROPIC_API_KEY unset instead of an empty string can make the authentication method ambiguous and cause an error. Always explicitly set it to "".
  • To switch to a different model, just change ANTHROPIC_MODEL to the model ID on OpenRouter (e.g. anthropic/claude-opus-4-8, openai/gpt-5, etc.).
  • Tool search optimization (ENABLE_TOOL_SEARCH) is disabled by default on non-Anthropic hosts. Add ENABLE_TOOL_SEARCH=true if you need it.

I Built “llmglot” an LLM API Translation Proxy That Connects Claude Code, Codex, and Gemini

In AI development, people are increasingly struggling more with API specification differences than with the models themselves.

Claude Code uses the Anthropic Messages API. OpenAI-based tools use the Chat Completions API or the Responses API. Gemini has its own proprietary API, and local LLM environments such as Ollama and LM Studio provide OpenAI-compatible APIs.

Even when the model you want exists, you may not be able to connect to it because the API specifications differ. You need to rewrite SDKs, implement translation layers, and separate configurations for each environment.

llmglot is the tool that solves these problems.

GitHub: https://github.com/Himeyama/llmglot

What is llmglot?​

llmglot is a proxy server that converts multiple LLM APIs back and forth.

It accepts Anthropic Messages API, OpenAI Responses API, OpenAI Chat Completions API, Gemini API, and more, then appropriately converts and forwards them to the upstream API.

In other words, even if the API specification required by the client does not match the API specification of the model you actually want to use, you can still use it.

Supported Scope​

On the client side, it supports:

  • Claude Code
  • Anthropic SDK
  • OpenAI SDK
  • Responses API clients
  • Gemini SDK

On the upstream side, it can connect to:

  • Ollama
  • LM Studio
  • OpenAI
  • Gemini
  • OpenRouter
  • Azure OpenAI
  • vLLM

For example, it enables connections such as:

  • Claude Code → Ollama
  • OpenAI SDK → Gemini
  • Responses API → Chat Completions API

Connecting Claude Code to a Local LLM​

One use case for llmglot is connecting Claude Code to a local LLM.

For example, if you are using Ollama, start it with:

CHAT_BASE_URL=http://localhost:11434/v1 llmglot

Then simply change Claude Code’s connection target to llmglot, and you can use a local LLM from Claude Code.

Being able to try a code agent without using an expensive API is extremely appealing.

(Note: Ollama actually supports the Messages API, so a proxy is not really necessary.)

Supports the Responses API Too​

Recently, more and more tools have been using the Responses API.

llmglot implements the /v1/responses endpoint and supports not only HTTP but also WebSocket.

That makes it easy to connect with Responses API-based clients such as the Codex CLI.

Useful Logging Features​

llmglot includes a log display feature.

The information you can check includes:

  • Model name
  • Provider
  • Input token count
  • Output token count
  • Cache usage
  • Estimated cost
  • Generation speed

In environments where multiple LLMs are used, the benefit of centrally managing usage information is significant.

Differences from LiteLLM

At this point, the question is: how is this different from LiteLLM?

Both are software that sits between LLMs, but the direction they aim for is very different.

LiteLLM’s Approach​

LiteLLM unifies many LLM providers into OpenAI format.

In other words:

App
↓
LiteLLM
↓
Each LLM provider

You could say it is a mechanism for application developers to use a unified API.

llmglot’s Approach​

llmglot, on the other hand, is structured like this:

Claude Code
Codex CLI
Gemini SDK
↓
llmglot
↓
Each LLM provider

Its goal is to translate the client-side API specification.

Comparing with Claude Code​

Claude Code uses the Anthropic Messages API.

LiteLLM is basically centered on OpenAI-compatible APIs, so connecting Claude Code directly is difficult.

llmglot, on the other hand, accepts the Anthropic Messages API directly.

That means the following configuration is possible:

Claude Code
↓
llmglot
↓
Ollama

This is a very major feature of llmglot.

Which Should You Choose?​

LiteLLM is a good fit for:

  • People developing AI applications
  • People who want to use the OpenAI SDK as a unified interface
  • People who want load balancing or fallback

llmglot is a good fit for:

  • People who want to run Claude Code with a different model
  • People who want to use local LLMs from existing clients
  • People who want to convert the Responses API to another API
  • People who do not want to rewrite SDKs

Conclusion​

In the LLM world, API differences are becoming a bigger problem than the models themselves.

You want to use Claude Code, but with Ollama. You want to use the OpenAI SDK, but with Gemini. Demands like these will likely continue to grow.

llmglot sits in the middle and absorbs the differences in API specifications.

  • Claude Code → Ollama
  • OpenAI SDK → Gemini
  • Responses API → Chat Completions API
  • Gemini API → OpenAI-compatible API

If LiteLLM is a “unified API for developers,” llmglot could be described as a “client-compatible proxy.”
What is Coreutils for Windows

In June 2026, Microsoft officially released Coreutils for Windows.

winget install Microsoft.Coreutils

The Microsoft.Coreutils package installed with this command is an official Microsoft project that enables UNIX-style commands commonly used on Linux and macOS—such as ls, cp, rm, and cat—to run natively on Windows.

This article summarizes the project overview, supported commands, limitations, and differences from WSL and PowerShell.

Overview

Microsoft.Coreutils is a set of command-line tools for Windows maintained by Microsoft.

Internally, it is built on:

  • uutils/coreutils
  • findutils
  • grep

and implemented in Rust.

Microsoft describes the project’s goal as:

reducing friction for developers who move between Linux, macOS, WSL, containers, and Windows

Installation

It can be installed easily from WinGet.

winget install Microsoft.Coreutils

WinGet is the package manager built into Windows, and it can automatically download and install the specified package.

After installation, it can be used as ordinary commands.

ls
cat file.txt
grep keyword log.txt
cp source.txt backup.txt

Main Available Commands

Representative commands are as follows.

CategoryExample Commands
File listingls
File copycp
File movemv
File deletionrm
Display contentscat
Working directorypwd
Create directorymkdir
Sleepsleep
Pipe processingtee
Searchgrep, find

If you are a Linux user, you can use familiar commands as they are.

PowerShell Collision Issues

This is the biggest point of caution!

PowerShell already has aliases and built-in commands with the same names.

Examples:

CommandIssue
lsConflicts with a PowerShell alias
cpConflicts with Copy-Item
catConflicts with Get-Content
rmConflicts with Remove-Item
pwdConflicts with Get-Location

Therefore, even if you run:

ls

it does not necessarily invoke the Coreutils version.

Microsoft recommends using PowerShell 7.4 or later.

Windows-Specific Limitations

Although it aims for Linux compatibility, there are limitations due to Windows internals.

1. No POSIX Signals​

Linux’s mechanisms for:

kill
SIGTERM
SIGKILL

do not exist on Windows.

Therefore,

kill
timeout

are not provided at this time.

2. No /dev/null​

Linux:

grep error log.txt > /dev/null

Windows:

grep error log.txt > NUL

will be used instead.

3. Differences Between ACL and POSIX Permissions​

Windows uses ACL-based permission management.

Therefore, commands such as:

chmod
chown
chgrp

are not provided.


Reading is possible, but creating new ones requires:

  • Developer Mode
  • Administrator privileges

Main Commands Not Provided

Microsoft intentionally excludes some commands.

Those that conflict with Windows​

  • dir
  • more
  • paste
  • whoami
  • expand

Those with strong POSIX dependencies​

  • chmod
  • chown
  • chgrp
  • chroot
  • nohup
  • stty
  • tty
  • who

Not yet implemented at this time​

  • kill
  • timeout
  • dd

Differences from WSL

A common comparison is with WSL (Windows Subsystem for Linux).

ItemMicrosoft.CoreutilsWSL
Installation costVery lowRequires setting up a Linux environment
Startup speedNativeHas a virtualized layer
Linux compatibilityPartialVery high
Bash environmentNoneAvailable
apt usageNot possiblePossible
Shell script compatibilityLimitedHigh

WSL is “Linux itself,” whereas Coreutils is “a toolset for using Linux-style commands on Windows.”

Recommendation for Makefile

Background and Problem Awareness​

In daily work, when automating data transformation with Python scripts, you often run into the following issues:

  • Only part of the source data has been updated, but you end up rerunning everything and wasting time.
  • It is unclear which steps depend on which files, making execution order and missed steps hard to manage.
  • It is difficult to tell which outputs will be affected when a script changes.

A Makefile is a tool that natively provides "dependencies" and "incremental rebuilds" (rerunning only the changed parts), and can solve these issues with just a small amount of notation.

Basics of Make​

  • Target: the artifact to be generated (e.g. output/report.csv)
  • Dependencies: the files required for generation (e.g. data/clean/*.csv and scripts)
  • Recipe: the command used to generate it (e.g. python scripts/aggregate.py ...)

Make runs the recipe only when the dependencies are newer than the target. This automatically reruns only the necessary parts when source data or Python scripts are updated.

Minimal Makefile Example​

The following is an example of incrementally processing raw data, cleaning it, and generating an aggregate report.

# Makefile
SHELL := bash
.SHELLFLAGS := -eu -o pipefail -c
.DELETE_ON_ERROR:
.ONESHELL:
.DEFAULT_GOAL := all

RAW_DIR := data/raw
CLEAN_DIR := data/clean
OUT_DIR := output

RAW := $(wildcard $(RAW_DIR)/*.csv)
CLEAN := $(patsubst $(RAW_DIR)/%.csv,$(CLEAN_DIR)/%.csv,$(RAW))
REPORT := $(OUT_DIR)/report.csv

# Directories are order-only dependencies (they are created if missing, but not used for rebuild checks)
$(CLEAN_DIR) $(OUT_DIR):
mkdir -p $@

# The aggregate report depends on the cleaned CSVs and the aggregation script
$(REPORT): $(CLEAN) scripts/aggregate.py | $(OUT_DIR)
python scripts/aggregate.py -i $(CLEAN_DIR) -o $@

# Generate the corresponding clean CSV from each raw CSV
$(CLEAN_DIR)/%.csv: $(RAW_DIR)/%.csv scripts/clean.py | $(CLEAN_DIR)
python scripts/clean.py -i $< -o $@

.PHONY: all clean status

all: $(REPORT)

clean:
rm -rf $(CLEAN_DIR) $(OUT_DIR)

# Helper to check what will be rebuilt
status:
@echo "RAW : $(RAW)"
@echo "CLEAN : $(CLEAN)"
@echo "REPORT: $(REPORT)"
@echo
@echo "Dry-run (what would run):"
@$(MAKE) -n all

With this structure, the following becomes possible:

  • When data/raw/foo.csv is updated, only the corresponding data/clean/foo.csv is regenerated.
  • When scripts/clean.py is updated, only the cleaning steps that are needed are rerun.
  • When scripts/aggregate.py is updated, only the aggregate report is rerun.

How It Works​

# First run (generate everything)
make -j

# Part of the raw data is updated (only that file's cleaning and the report are rerun)
touch data/raw/a.csv
make -j

# The cleaning script is updated (all cleaning steps and the report are rerun)
touch scripts/clean.py
make -j

# The aggregation script is updated (only the report is rerun)
make

To check in advance what will run, make -n is useful.

Guidelines for Designing Script Dependencies​

  • For each rule, it is important to explicitly list the Python script it directly invokes as a dependency.
  • If you split code across multiple modules, include in the dependencies the modules imported by the target rule so that changes propagate correctly. A simple approach is to collect all Python files in the relevant directory into a variable and add them to the dependencies.

Example (simple approach):

PY_SRCS := $(wildcard scripts/**/*.py) $(wildcard scripts/*.py)

$(CLEAN_DIR)/%.csv: $(RAW_DIR)/%.csv $(PY_SRCS) | $(CLEAN_DIR)
python scripts/clean.py -i $< -o $@

Parallel Execution and Speedup​

  • make -j can parallelize independent file transformations. The more data points you have, the more effective this becomes.
  • The more finely you split intermediate outputs, the more effective incremental builds become, avoiding full recomputation.
  • If I/O is the bottleneck, combine this with compressed formats, file partitioning, or a local SSD.

Practical Tips for Production Use​

  • Treat directory creation as an order-only dependency (| dir) to avoid unnecessary rebuilds.
  • Enable .DELETE_ON_ERROR so incomplete outputs are not left behind on failure.
  • Standardize the common entry point with .DEFAULT_GOAL := all so that make works out of the box.
  • For debugging, use make -n (show without running), make --trace (show why something runs), and make -d (verbose logs).
  • Use .PHONY: clean for cleanup, and be careful to delete only generated artifacts.

Virtual Environments and Dependencies (Optional)​

Python execution environments can also be managed with Make.

VENV := .venv
PY := $(VENV)/bin/python

$(VENV)/bin/python: requirements.txt
python3 -m venv $(VENV)
$(VENV)/bin/pip install -r requirements.txt
touch $@

# Use $(PY) in subsequent recipes
$(CLEAN_DIR)/%.csv: $(RAW_DIR)/%.csv scripts/clean.py | $(CLEAN_DIR) $(VENV)/bin/python
$(PY) scripts/clean.py -i $< -o $@

$(REPORT): $(CLEAN) scripts/aggregate.py | $(OUT_DIR) $(VENV)/bin/python
$(PY) scripts/aggregate.py -i $(CLEAN_DIR) -o $@

If requirements.txt is updated, only the necessary portion will be set up again.

Summary​

  • A Makefile is a tool that automates "explicit dependencies" and "incremental rebuilds," greatly improving the reliability and development speed of data transformation pipelines.
  • By correctly linking source data, scripts, and generated outputs, and by splitting processing into smaller steps, only the affected scope of updates is quickly recomputed.
  • With minimal notation, you get reproducibility, parallelization, and observability, making everyday automation work much more comfortable.

Assigned a Custom Domain to a Subpath on Sakura Server with Cloudflare Workers

Background​

Sakura’s rental server "Lite Plan" offers an incredibly low price of 121 yen per month for a 36-month lump sum payment (165 yen per month for a 12-month lump sum). It's sufficient for hosting static files and CGI purposes, making it easy to use as personal storage.

However, the assigned domain will be a subdomain of username.sakura.ne.jp, so some ingenuity is required if you want to associate your custom domain with a specific path.

What I Want to Achieve​

When accessing https://app.example.com, the content from https://sakurauser.sakura.ne.jp/app/ should be displayed without changing the URL.

Why Simple DNS Settings Won't Work​

DNS CNAME records can only specify hostnames, and URLs that include paths like /app/ cannot be specified.

While it can be achieved using a redirect (301), the URL in the browser's address bar would change to sakurauser.sakura.ne.jp/flower/.

Using transparent proxy with Cloudflare Workers allows the URL to remain as app.example.com.

Prerequisites​

  • You must be registered with a custom domain on Cloudflare (e.g., example.com)
  • A free plan on Cloudflare is acceptable (up to 100,000 requests per day for free)

Steps​

1. Create a Worker​

  1. Cloudflare Dashboard → Workers & Pages → Create
  2. Select Start with Hello World!
  3. Enter the Worker name (e.g., storage-proxy)
  4. Click Deploy

2. Edit the Code​

After deploying, click Edit code and replace all with the following code.

export default {
async fetch(request) {
const url = new URL(request.url);
const target = new URL("https://sakurauser.sakura.ne.jp");
target.pathname = "/app" + url.pathname;
target.search = url.search;

const newRequest = new Request(target.toString(), {
method: request.method,
headers: request.headers,
body: request.body,
});

const response = await fetch(newRequest);

const newHeaders = new Headers(response.headers);
newHeaders.delete("content-security-policy");
newHeaders.delete("x-frame-options");

return new Response(response.body, {
status: response.status,
headers: newHeaders,
});
}
};

Summary​

  • Sakura's rental server Lite Plan is 121 yen per month and can sufficiently serve as a storage for static files.
  • However, assigning a custom domain to a subpath is not possible with standard DNS settings.
  • By using Cloudflare Workers as a transparent proxy, you can deliver content without changing the URL.
  • The Workers' code is only a few dozen lines, and it operates within the limits of the Cloudflare free plan.

Why "Multiples of 8" Are the Standard for Spacing in CSS

In modern UI design, the rule of setting "spacing in multiples of 8" is commonly used. This is not just a convention, but an empirical rule supported by the mathematical consistency of screen density, typography, and scale.

Addressing Various Screen Densities​

Modern displays have pixel ratios such as 1x, 1.5x, 2x, 3x, and 4x.

Value1x1.5x2x3x4x
8 px812162432
5 px57.5 ⚠️101520

Since 8 is divisible into integers for many scales, it minimizes blurring caused by subpixel rendering. Using values like 5 px can generate fractions like 7.5 px in a 1.5x environment, leading to inaccurate rendering.

Compatibility with Typography​

The default font size in browsers is 16 px (= 8 × 2). Line height is typically 1.5 times that, which equals 24 px (= 8 × 3).

By setting spacing in multiples of 8, the rhythm of the text can visually align more easily. The height of headings and body text matches the spacing grid, creating a well-organized vertical rhythm.

Ease of Creating Design Tokens​

--space-1: 8px;
--space-2: 16px;
--space-3: 24px;
--space-4: 32px;

The scale is simple, making it easy for designers and engineers to utilize as a common language. Material Design and Tailwind CSS also adopt this philosophy.

When a designer specifies "space-3," the engineer can confidently apply 24px. A consistent naming convention reduces the communication cost during code reviews.

The Option of a 4 px Base​

For UIs that require finer adjustments, a 4 px base (4, 8, 12, 16...) is also common. Tailwind CSS adopts a default 4 px base (p-1 = 4px).

The 4 px base is a subset of the 8 px base, so both can coexist without contradiction. It is effective to use 4 px units for small spacings within components, while using 8 px units for larger spacings between sections.

Conclusion​

The reasons for using multiples of 8 as the standard for spacing can be summarized in three points:

  1. Addressing Screen Density: It divides into integers across many pixel ratios, preventing subpixel blurriness.
  2. Consistency with Typography: Aligns with the default font size (16 px) and line height (24 px), creating a vertical rhythm.
  3. Consistency in Scale: A simple token system serves as a common language for designers and engineers.

New Feature: Mount S3 Buckets to EC2 Using Amazon S3 Files

Amazon S3 Files is a service that allows you to directly mount S3 buckets as an NFS file system on compute resources such as EC2. Data remains stored in S3 while enabling typical file operations (ls, cp, cat, etc.) for reading and writing.

What is S3 Files?​

S3 Files is a shared file system built on Amazon EFS, providing file system access to data stored in S3 buckets.

Key features include:

ItemDescription
ProtocolNFS 4.1 / 4.2
Supported ComputeEC2, Lambda, ECS, EKS
Concurrent ConnectionsUp to 25,000 compute resources
Read ThroughputUp to TB/second
IOPSOver 10 million / bucket
EncryptionTLS (in transit) + AWS KMS (at rest)
File System FeaturesPOSIX permissions, file locking, read-after-write consistency

How It Works​

S3 Files automatically loads accessed data to high-performance storage and provides it with low latency.

  • Small Files (default less than 128 KB): Read directly from high-performance storage
  • Large Files (1 MB and above): Stream directly from S3
  • Writing: Write to high-performance storage and automatically sync to S3

Data on high-performance storage is automatically deleted after a certain period of inactivity (default 30 days, configurable from 1 to 365 days).

Prerequisites​

  • AWS Account
  • EC2 Instance (Linux)
  • S3 Bucket (in the same region as EC2)
  • Two IAM Roles
    • For creating the file system: Permissions to read/write to the S3 bucket
    • For the EC2 instance: Attach the AmazonS3FilesClientFullAccess managed policy
  • Security Group: Allow communication on NFS port 2049

Creating IAM Roles​

Two IAM roles are required for S3 Files.

1. Role for Creating File Systems​

Automatically created when using the management console, so this step is not necessary

This is the role that allows S3 Files to access the bucket.

# Create role
aws iam create-role \
--role-name S3Files-FileSystem-Role \
--assume-role-policy-document '{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": { "Service": "s3files.amazonaws.com" },
"Action": "sts:AssumeRole"
}
]
}'

# Attach S3 Files client policy
aws iam attach-role-policy \
--role-name S3Files-FileSystem-Role \
--policy-arn arn:aws:iam::aws:policy/AmazonS3FilesClientFullAccess

Specify this role with --role-arn when creating the file system.

2. Role for EC2 Instance​

Failure to attach the IAM role will result in mount failure

Create the following role in CloudShell.

# Create role
aws iam create-role \
--role-name EC2-S3Files-Role \
--assume-role-policy-document '{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": { "Service": "ec2.amazonaws.com" },
"Action": "sts:AssumeRole"
}
]
}'

# Attach S3 Files client policy
aws iam attach-role-policy \
--role-name EC2-S3Files-Role \
--policy-arn arn:aws:iam::aws:policy/AmazonS3FilesClientFullAccess

# Create and attach instance profile
aws iam create-instance-profile \
--instance-profile-name EC2-S3Files-Profile

aws iam add-role-to-instance-profile \
--instance-profile-name EC2-S3Files-Profile \
--role-name EC2-S3Files-Role

Attach this role to the instance.

Setup Steps​

1. Prepare the S3 Bucket​

Create a general-purpose bucket in the S3 console. You can also use an existing bucket.

However, versioning must be enabled for the bucket.

2. Create the File System​

If Creating from the Console​

alt text

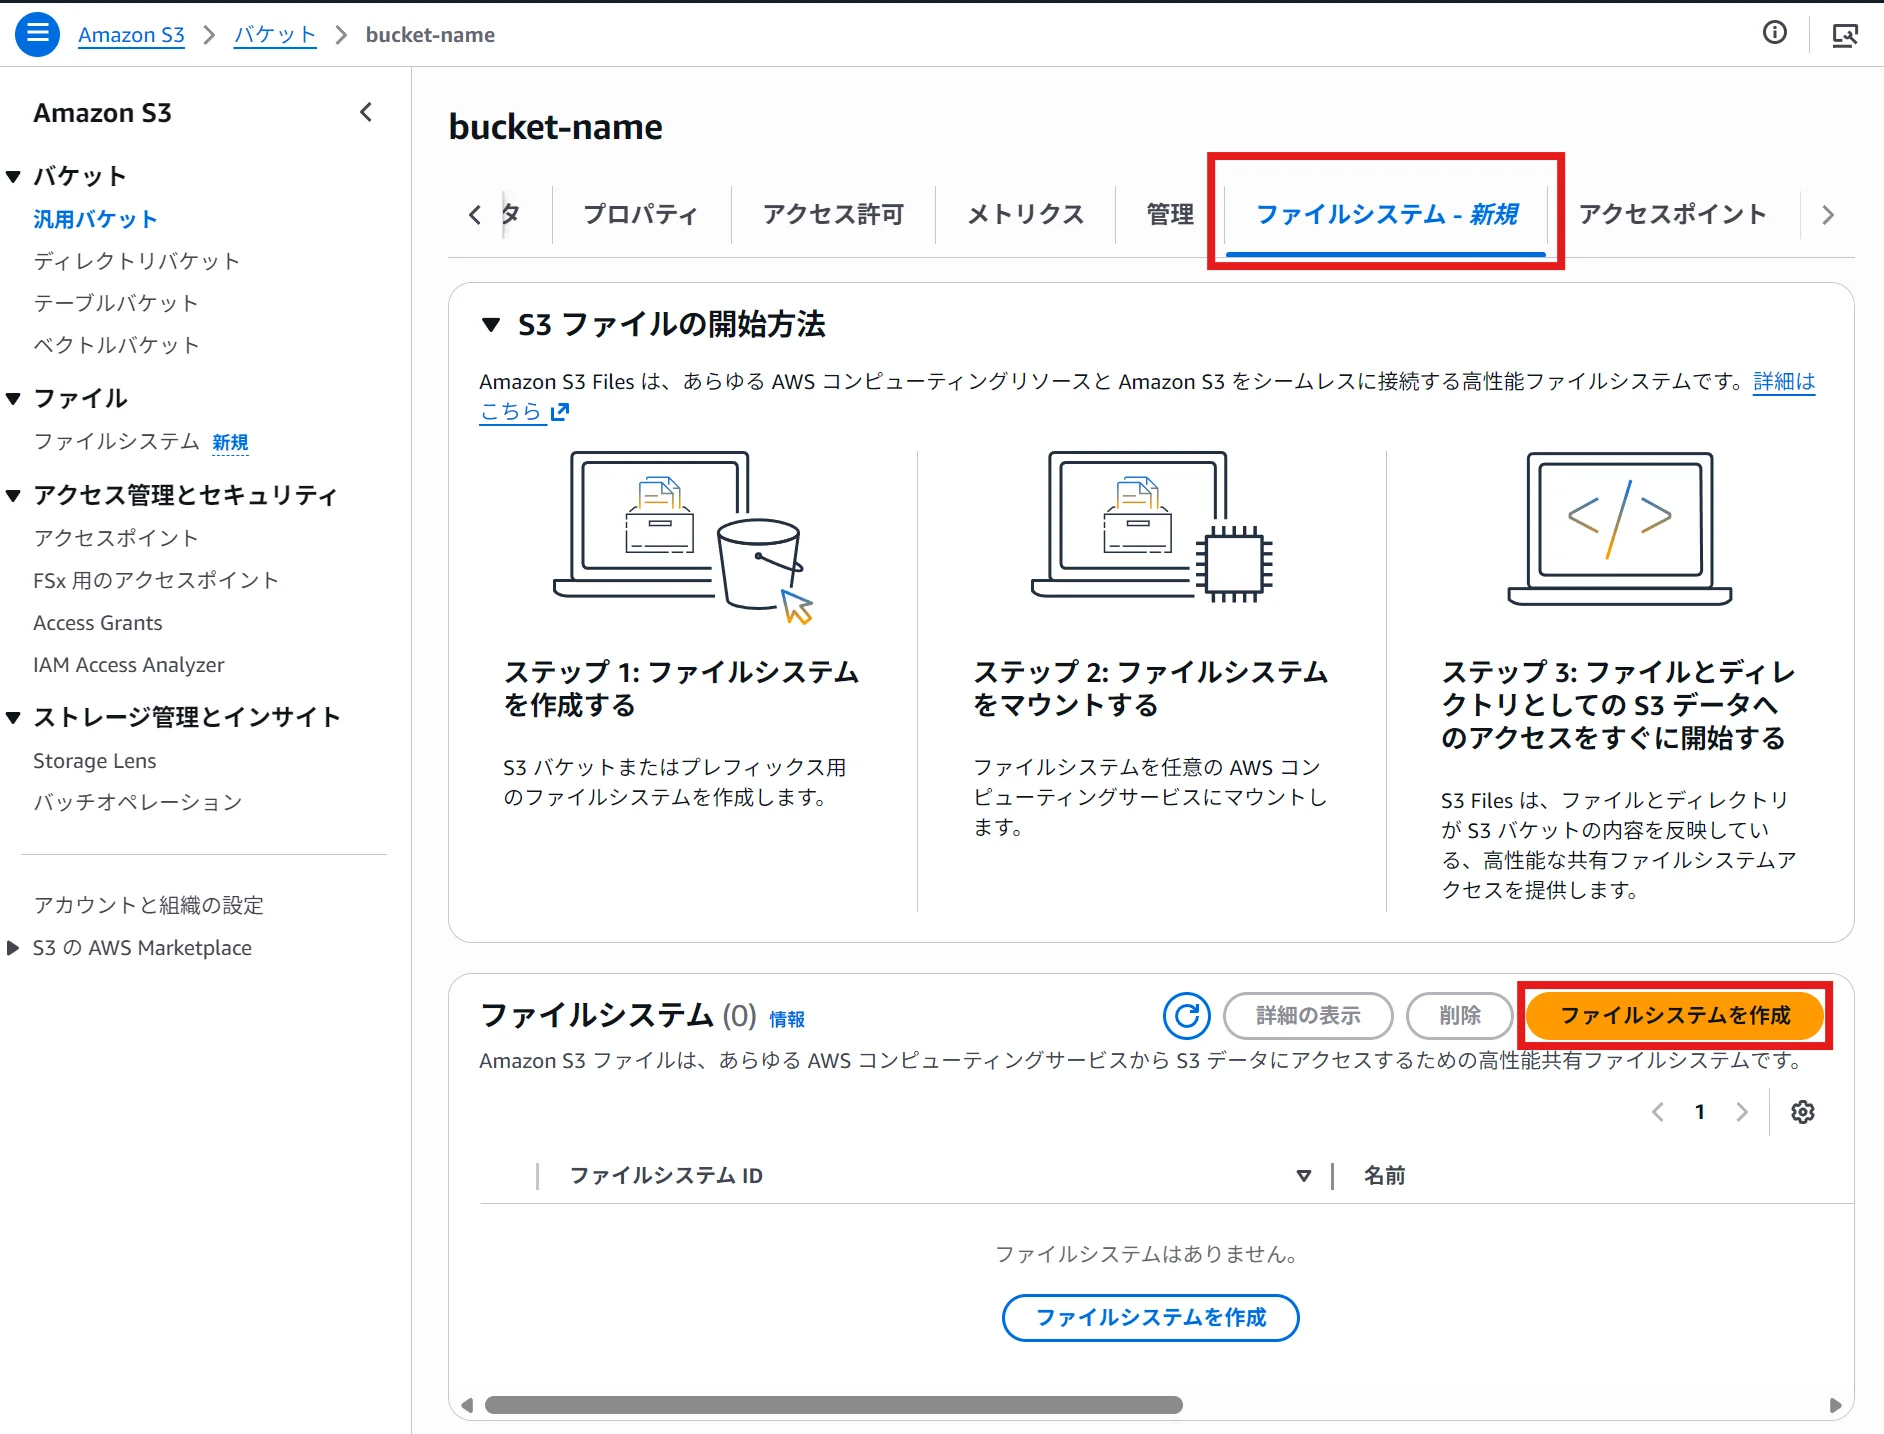
  1. Select the bucket in the S3 console
  2. Click on the "File Systems" tab → then click "Create File System"

Creating from the console automatically creates mount targets and access points in all AZs.

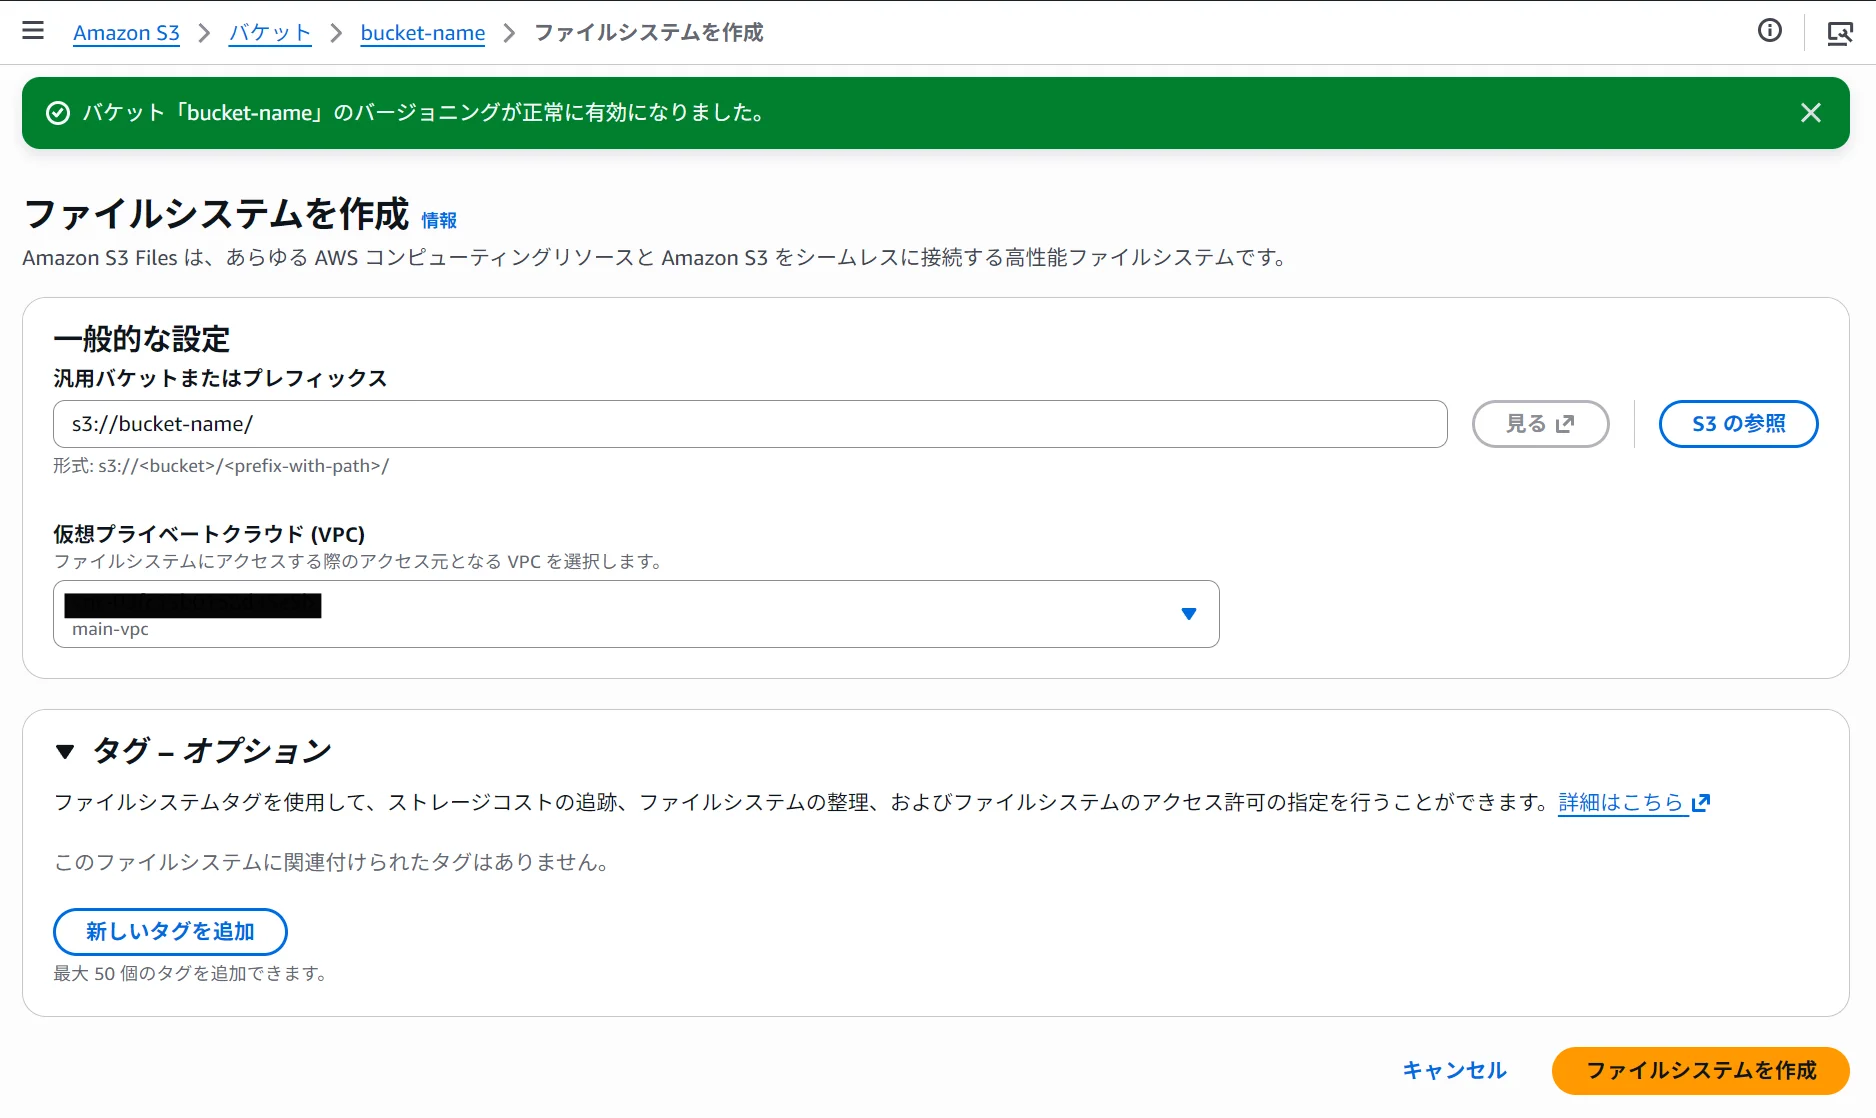
alt text

  1. Specify the prefix and VPC, and click "Create File System."

Record the output file system ID (e.g., fs-0123456789abcdef0).

3. Mount on the Instance​

In the terminal, execute the following:

# Create mount point
sudo mkdir /mnt/s3files

# Mount
sudo mount -t s3files fs-0123456789abcdef0:/ /mnt/s3files
note

If the mount fails, execute the following command and retry.

sudo dnf install -y amazon-efs-utils # Amazon Linux, RHEL
# sudo apt install -y amazon-efs-utils (Ubuntu, Debian)
note

If there is connectivity issue when executing the dnf command, set up an S3 endpoint (gateway) and assign it to the same AZ as the instance.

Ensure that the route table for the S3 endpoint matches the subnet where the instance is located.

To verify the mount:

df -h /mnt/s3files

You should see output similar to the following:

Filesystem Size Used Avail Use% Mounted on
<s3files-dns> 8.0E 129M 8.0E 1% /mnt/s3files

4. Perform Functionality Checks​

cd /mnt/s3files

# Create a file
sudo sh -c 'echo "Hello, s3 Files!" > test.txt'

# Read the file
cat test.txt

# Create a directory
sudo mkdir test-directory

ls -la

# Copy the file
sudo cp test.txt test-directory/

cd test-directory/

# Check the file list
ls -la

The file you wrote will sync to the S3 bucket in about one minute. You can verify that the object has been created in the S3 console.

aws s3 ls s3://<bucket-name>/

Setting Up Auto-Mount​

To maintain the mount after a reboot, add the following line to /etc/fstab.

# Add to /etc/fstab
fs-0123456789abcdef0:/ /mnt/s3files s3files _netdev,nofail 0 0

_netdev is an option that ensures the mount occurs after the network connection is established and is required. Adding nofail prevents the instance from becoming unbootable in the event of mount failure.

Pricing​

The pricing for S3 Files is composed of the following components:

  • High-Performance Storage Usage: The storage fees for data on the file system
  • File System Access Fees: Read and write operations to high-performance storage
  • S3 Request Fees: Only the S3 GET charges apply when reading files over 1 MB directly from S3

It operates on a usage-based pricing model with no provisioning required, and according to AWS, it can achieve cost savings of up to 90% compared to traditional data copying between S3 and file systems.

Summary​

  • S3 Files allows you to mount S3 buckets as an NFS file system on EC2
  • Data remains stored in S3 while enabling typical file operations like ls, cat, and cp
  • Low latency is achieved through caching on high-performance storage, and data that goes unused is automatically evicted
  • Configuring auto-mount using /etc/fstab ensures persistence after a reboot

References​